
Case Study
How Motive made ML model evaluation ~200× faster with Anyscale
A pipeline with GPU inference next to CPU-heavy video processing and analysis, and a measurement loop cheap enough to find out where to split it instead of arguing about it.

~200x
faster parameter sweeps
9x
distributed throughput on 16 GPUs vs 1
3.8x
faster reruns when only analysis changes
~20x
44 variants fan-out in one pass over the data
Motive builds AI-powered safety products for physical-operations fleets. Before a computer-vision model reaches a vehicle, Motive's team validates it against a large corpus of recorded driving footage.
What ships isn't a single model. It is a feature, and a feature is a graph: several perception models feed a fusion model, which feeds thresholds and temporal logic, which decide whether an alert fires. A candidate change to any one node only means something once it has been scored through the whole graph, over the whole corpus. Engineers rarely test one change at a time either: three model candidates on one node and two on another is six full replays, and a single threshold swept over a few dozen values is a few dozen more.
Motive's original evaluation loop ran on one machine and ran every configuration end to end. At that rate, a routine sweep took more than a day.
LinkA heterogeneous pipeline
Each evaluation mixes three very different kinds of work: fetching and decoding video (I/O and CPU), running models (GPU), and analysis (CPU). They need different hardware, scale differently and change at different rates: models change rarely, thresholds and analysis logic constantly.
Ray Data can run all three in one streaming pipeline. Each stage declares the resources it needs, and Ray schedules it onto the right nodes of a cluster that mixes GPU and CPU machines. That shifted the team's question from how to build a distributed pipeline to where the stage boundaries should go.
Tim Cheng | Engineering Manager, Motive

LinkSettling design questions with experiments
The textbook answer is one stage per resource profile. Motive built that design, then built a second design with fetch, decode and inference fused into a single GPU actor. Both designs are a few lines of Ray Data (simplified):
1import ray
2
3# A — one stage per resource profile
4ds = ray.data.read_parquet(manifest)
5ds = ds.map_batches(FetchFrames,  num_cpus=1,    concurrency=64)
6ds = ds.map_batches(DecodeFrames, num_cpus=2,    concurrency=32)
7ds = ds.map_batches(RunModels,    num_gpus=0.25, concurrency=64)
8ds = ds.map_batches(FuseAndScore, num_cpus=1,    concurrency=32)
9
10# B — fetch and decode fused into a stateful GPU actor
11class InferActor:
12    def __init__(self):
13        self.models = load_models()                          # once per actor
14
15    def __call__(self, batch):
16        frames = [decode(fetch(p)) for p in batch["path"]]  # I/O + CPU
17        return {"scores": self.models(frames)}                # GPU
18
19ds = ray.data.read_parquet(manifest)
20ds = ds.map_batches(InferActor,   num_cpus=2, num_gpus=0.25, concurrency=64)
21ds = ds.map_batches(FuseAndScore, num_cpus=1, concurrency=32)
Both ran on the same cluster with the same budget (16 GPUs and 160 CPU slots, allocated differently), and each was tuned as well as the team could get it. The modular design lost consistently. Decoding expands a video by one to two orders of magnitude, and design A sends those decoded frames through the object store at every stage boundary. Design B keeps them in the actor's memory. The boundary that did pay off sits between inference and analysis, where only kilobytes of scores cross:
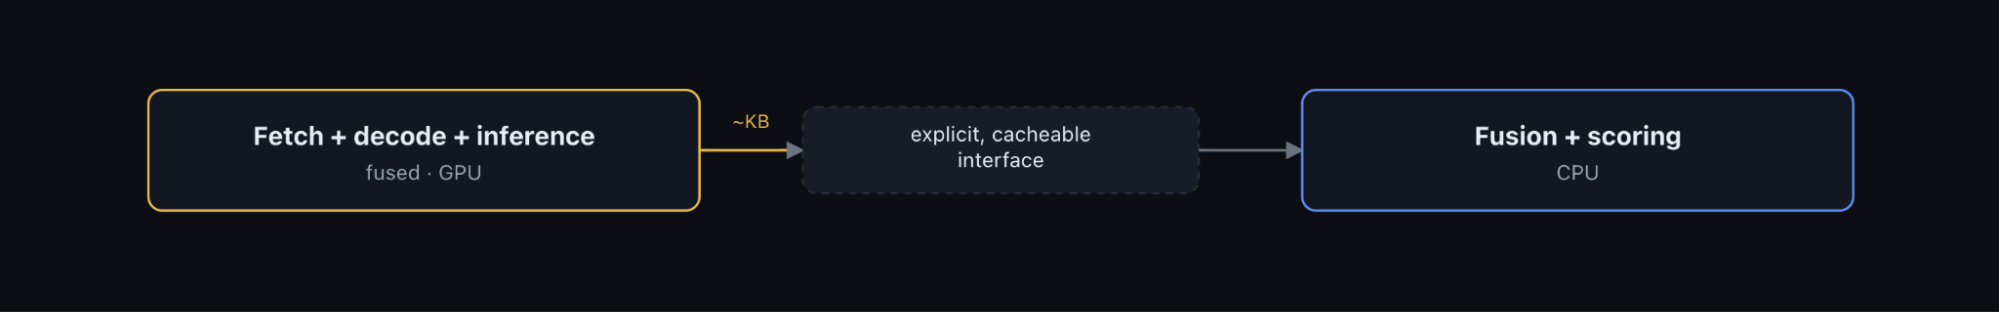 Only inference scores cross the inference–analysis boundary: kilobytes per item, against hundreds of megabytes of decoded frames at the other candidate boundary.
Two more experiments shaped the system, and each was a one-line configuration change on Anyscale:
GPU | Videos / s | $ / 1k videos |
|---|---|---|
T4 | 0.351 | 0.77 |
L4 (~2.5× faster on paper) | 0.381 | 1.03 |
8% faster, 34% more per video. Model inference was only about an eighth of the GPU stage; the rest was fetching and decoding. AWS on-demand list prices.
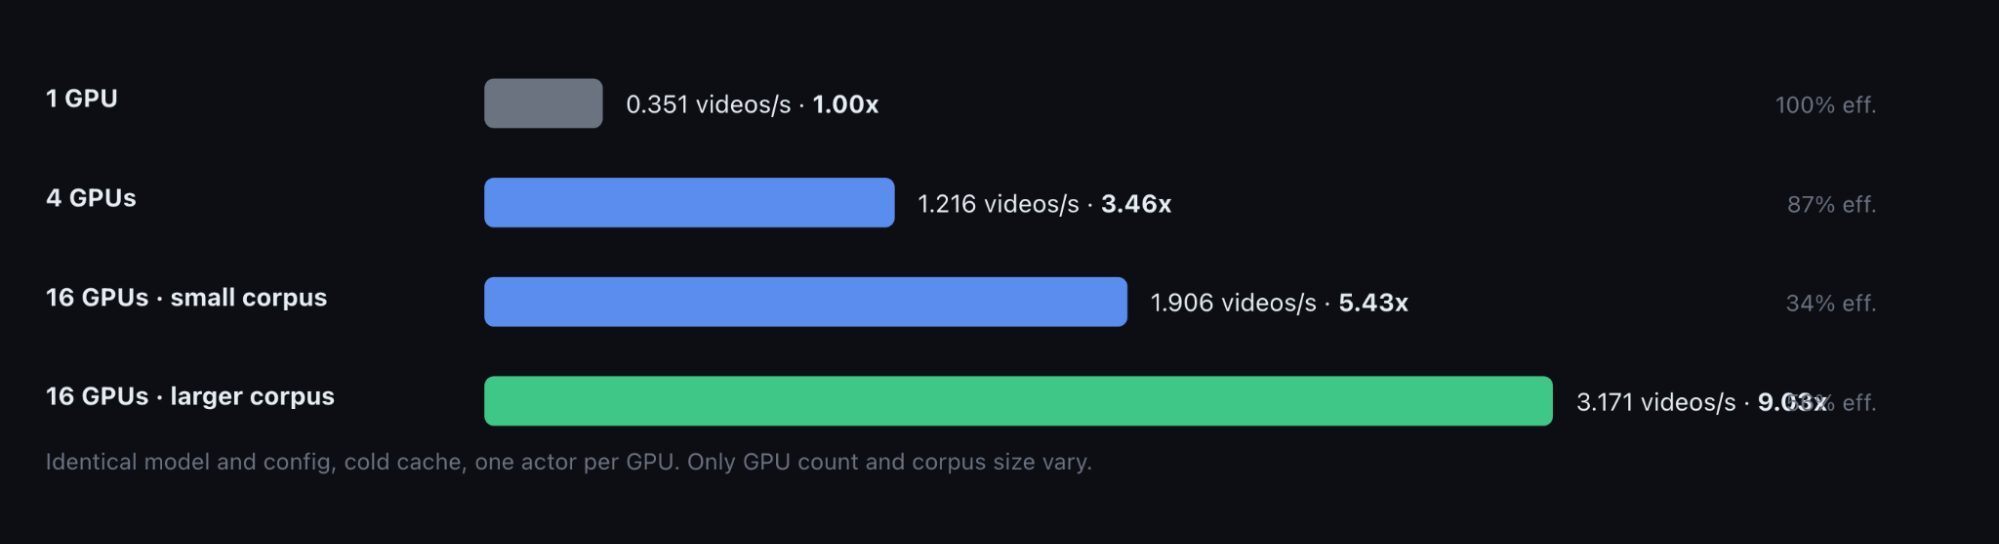 Measured scaling. Efficiency is scaling ÷ GPU count.
Scaling holds at 87% efficiency to 4 GPUs and reaches 9× at 16 GPUs on a larger corpus. On small corpora, fixed startup dominates: about 262 s to autoscale four nodes from zero and load models into sixteen actors. The measurements also exposed a real scaling loss at 16 GPUs (68% marginal efficiency), which put the asymptote near 10.8× rather than a linear 16×.
Every benchmark behind this case study, including both pipeline designs, both GPU types and three cluster sizes, cost 18.68 GPU-hours, about $20.
LinkWhat Anyscale provides
Heterogeneous compute in one pipeline.
Each stage declares its own num_gpus and num_cpus. The GPU inference pool and the CPU analysis pool are sized and tuned independently on one cluster that mixes GPU and CPU nodes, so no GPU sits allocated to CPU-only work.
A distributed data plane.
Ray Data partitions the corpus into blocks, rebalances work, retries failed blocks, streams data larger than memory, and applies backpressure so readers don't outrun the GPUs. That is why going from one GPU to sixteen was a config change.
Stateful actors.
Models load once per actor, in __init__, and serve many batches. Without this the fused design would reload models on every batch and lose its advantage.
Fractional GPUs.
A resource request can be a fraction: in production, Motive runs five inference actors per GPU (num_gpus=0.2), so one actor can wait on storage while another computes. No custom scheduler; it is one number in a resource declaration.
Autoscaling from zero.
Anyscale starts the cluster when a job is submitted and scales it back down afterwards. Motive keeps no standing cluster, so idle time costs nothing, and the cold-start price (~262 s at 16 GPUs) is measurable and predictable.
Hardware as configuration.
T4 versus L4, 1 versus 16 GPUs, and CPU-to-GPU ratios are compute-config changes, not infrastructure projects. That is what made the experiments above cheap enough to run.
Tim Cheng | Engineering Manager, Motive
LinkResults
The shipped system adds two more ideas on top of Anyscale. Inference output is cached at the inference–analysis boundary (median 3.8× on a warm rerun across seven matched pairs). And parameter lists in the analysis config fan out inside a single pass, so every variant shares one read and one inference result. A real iteration uses all of this together: the first run on a new model is cold and inference-bound, so it runs across 16 GPUs and caches its output. Every run after that is warm and fans out across all variants.
|
Workflow |
Step |
Time |
|---|---|---|
Before |
44 × end-to-end run on 1 GPU, no cache, no fan-out |
35.8 h |
With Anyscale |
1 · cold run on 16 GPUs, inference cached |
10.2 min |
2 · one warm job, 44 variants fanned out |
3.1 min |
|
|
Total |
13.3 min · ~160× |
Inference and analysis times measured on this corpus. Step 2 applies the 2.25× fan-out cost ratio measured across 20 production jobs. Per-job startup is excluded on both sides. The same arithmetic on a 5,000-video corpus gives ~300×; the ratio grows with corpus size, cluster size and sweep breadth.
A sweep that took more than a day now finishes in the time of a coffee break. Model evaluation turned from a gate the team ran before a release into a tool they use while they are still deciding what to try.
Tim Cheng | Engineering Manager, Motive
LinkWhy it wouldn't have happened without Anyscale
The original loop ran on one machine not for lack of hardware, but because distributing it meant writing a scheduler, corpus partitioning, retries, backpressure and separately sized CPU and GPU worker pools, plus a way to provision and tear down mixed clusters. Each of those is a project in its own right, and none of them is the team's actual job.
The experiments matter just as much. Comparing two pipeline designs at an equal budget, three cluster sizes and two GPU types would each have needed its own harness. Without that, the choice of pipeline design would have been made in a design review, and the textbook design would have won. On Anyscale, each experiment was a code or config change on the same substrate, and the whole programme cost about $20.
LinkWhat's Next
Looking ahead, Motive is expanding its AI platform in several directions: building a Driver Foundation Model trained on billions of dashcam data points currently sitting unused in their data lake, migrating cloud inference workloads to a more flexible serving architecture, and pushing toward larger and more complex models that will require training across many more nodes than their current workloads demand. As the fleet grows and the models become more sophisticated, the infrastructure investments the team has made will need to scale with them.
Tim Cheng | Engineering Manager, Motive
“We shorten our model training from seventy hours to under seven hours, and our testing time from three days to within an hour, and we're seeing significant speed-ups. That's what lets us go from one or two model iterations per release to ten or more."
Tim Cheng
Engineering Manager, Motive
